None defined yet.
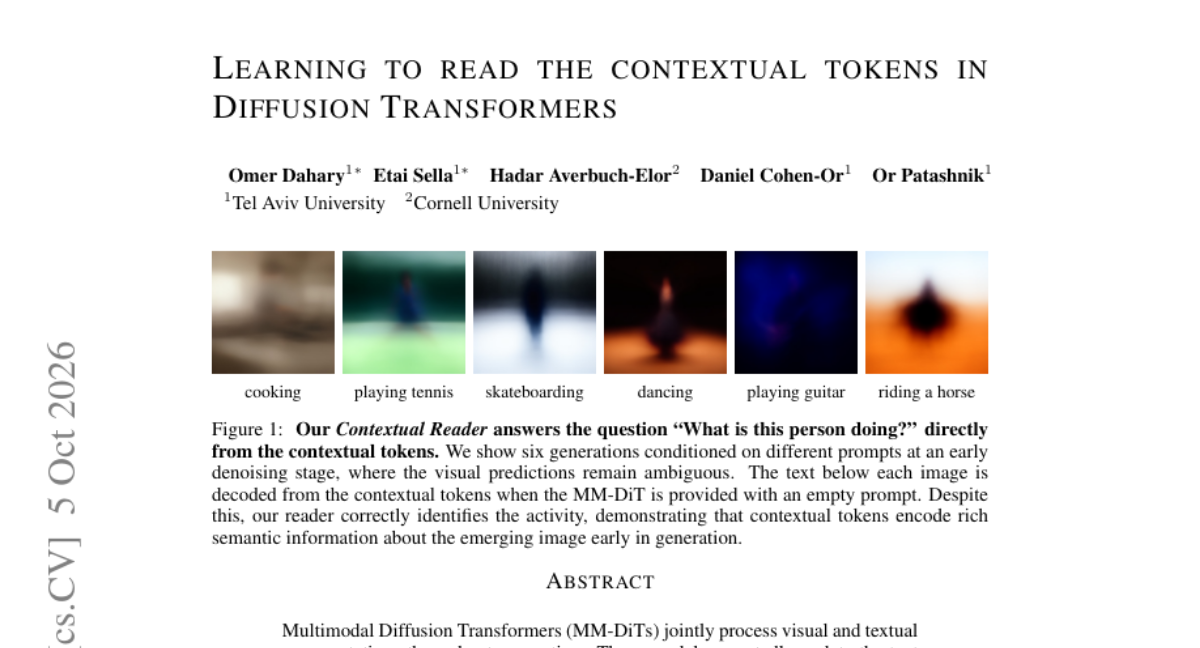
Learning to Read the Contextual Tokens in Diffusion Transformers
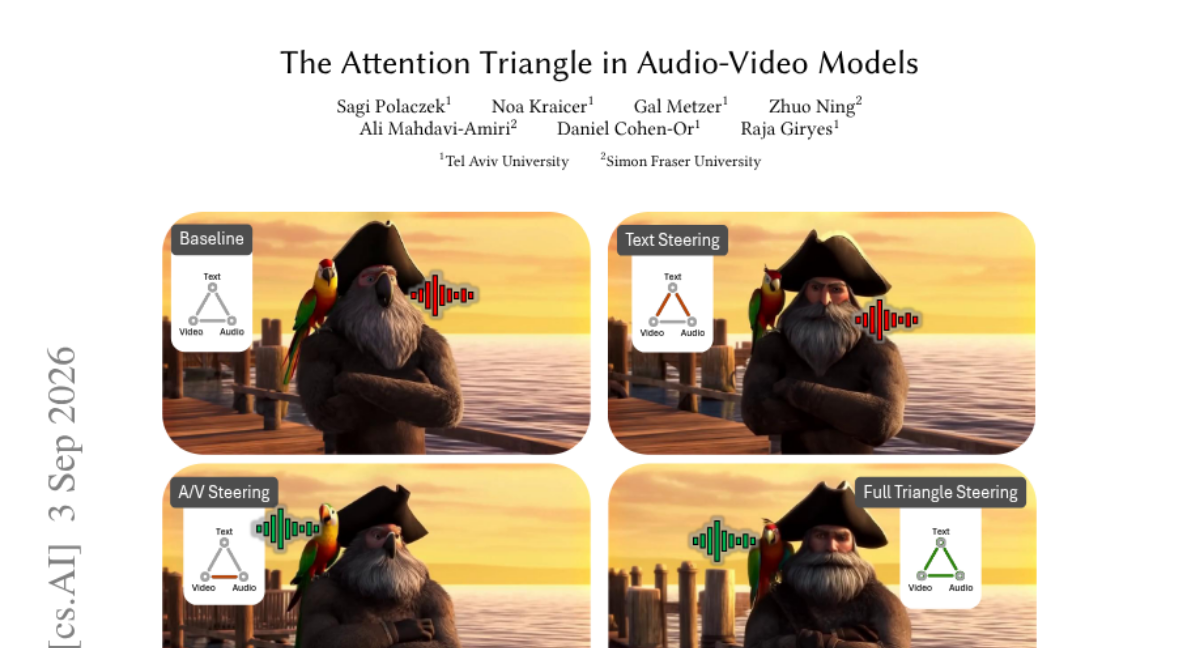
The Attention Triangle in Audio-Video Models